Data Engineering Services
best for
Companies generating data but missing the infrastructure to use it — before it becomes a liability.
service 06 / 06 · data
Data Solutions
- Data Pipelines & ETL/ELT
- Data Lakehouse Architecture
- Cloud Data Migration
in short
Bitlogs Technologies is a software development company that builds data pipelines, lakehouse architecture, and ML-ready data infrastructure for startups and growing businesses. Based in Lahore, Pakistan and serving clients in the US, Canada, and worldwide, Bitlogs delivers production data platforms on Azure and AWS — with founder-led engineering, fixed scopes, and a 30-day post-launch warranty.
If any of this sounds familiar, you’re who we build for.
We have data in six systems and no one trusts any of them.
We want to move to AI but the data isn't clean enough to do anything reliable with.
Our data pipeline breaks whenever a source changes something upstream.
We're still on-premise and the migration feels too risky to attempt.
Concrete deliverables. Nothing abstract.
- 01
Data Pipelines & ETL/ELT
Extract, transform, and load — built to handle schema drift, failed sources, and high volumes without someone watching it. Failures surface with alerts, not after-the-fact damage.
- 02
Data Lakehouse Architecture
A single governed store on Azure (Databricks / Fabric) or AWS (S3 + Glue + Athena) with Delta Lake ACID transactions. ML-ready, query-optimized, access-controlled.
- 03
Cloud Data Migration
On-premise or siloed systems moved to Azure, AWS, or GCP. Row counts and checksums validate every move. Nothing gets to production until parity is confirmed.
- 04
Pipeline Orchestration & Monitoring
Airflow or Azure Data Factory orchestration with SLA-level alerting. If a pipeline misses a run at 2AM, you hear about it before your users do.
- 05
Data Governance & Quality Engineering
Catalogs, lineage tracking, access controls, and automated quality gates. Required for SOC 2, HIPAA, or any data room that needs to hold up under scrutiny.
- 06
ML-Ready Feature Engineering
Versioned feature stores integrated with your model pipeline. Models train on consistent, documented features — not ad-hoc queries that change between runs.
How an engagement actually runs.
Step 1: Data Audit
We map your sources, volumes, and failure points before writing a line of code. You get a clear picture of what's broken and why — not a sales pitch dressed up as a discovery call.
Step 2: Architecture First
Pipeline design, schema drift handling, and governance decisions made before build starts. Retrofitting these into an existing architecture is expensive. We don't do it that way.
Step 3: Build, Orchestrate, Validate
Pipelines built with orchestration wired in, quality checks at every layer, and row-level validation before data lands in production.
Step 4: Govern and Hand Over
Data catalog, lineage documentation, alerting runbooks, and access controls. Your team runs this on their own after handover. That's the goal.
Recognized tools. No mystery frameworks.
- Apache Airflow
- Azure Data Factory
- dbt
- PySpark
- Databricks
- Microsoft Fabric
- Delta Lake
- Python
- SQL
- Azure
- AWS
Where this fits, so you can self-identify.
E-Commerce
Unified order, inventory, and customer pipelines feeding real-time revenue dashboards — and ML-ready behavioral features for the recommendation layer you're building next.
FinTech & Payments
Transaction pipelines with fraud-detection feature stores, automated regulatory reporting, and an ACID-compliant lakehouse that holds up to an audit.
Healthcare & SaaS
HIPAA-compliant infrastructure, patient data ETL across fragmented source systems, and clinical datasets ready for model training without manual cleaning before each run.
Logistics & Supply Chain
Real-time shipment tracking pipelines, route optimization feature engineering, and fleet dashboards that pull from one source instead of three spreadsheets and a gut feeling.
We’ve shipped this kind of work.
AI-Powered SaaS · MVP Delivered
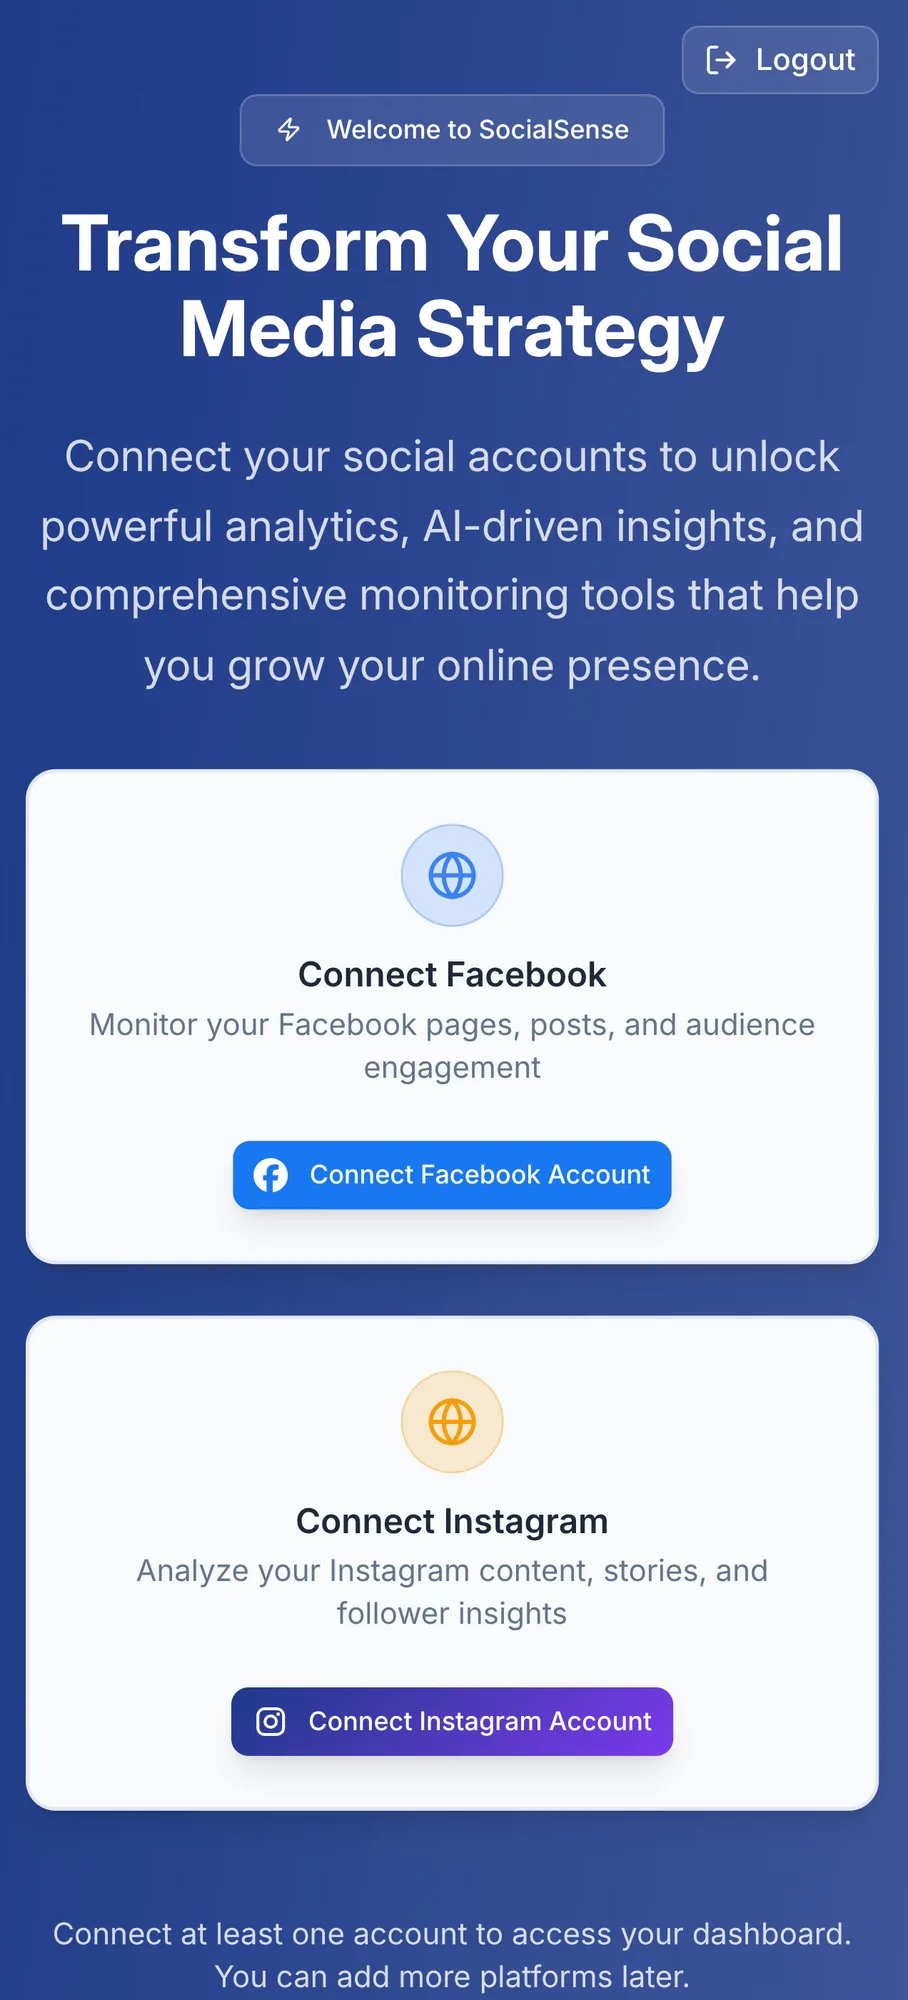
SocialSense
One AI dashboard for every social account
An AI-powered social media management platform — unified inbox, multilingual sentiment analysis, AI caption generation, and RAG-based automated responses, on a scalable microservice architecture.
Tags: AI / NLP · SaaS Dashboard · RAG Automation · Sentiment Analysis · Microservices
- Multilingual sentiment accuracy
- 75.6%
- Unified AI dashboard
- 1
- Core workflows shipped
- 10+

In our clients’ words.
Bitlogs helped turn SocialSense from a complex AI-based idea into a working product with real dashboards, automation, sentiment analysis, and a scalable technical architecture.
The questions clients are thinking but afraid to ask.
Almost always yes. AI models are only as good as the data they're trained on. We've seen companies spend six figures on ML that failed because the data foundation wasn't there.
A single well-scoped pipeline: 2–4 weeks. A full lakehouse migration: 8–16 weeks depending on data volume and source complexity. You'll get a specific estimate after a data audit.
Yes — a managed support tier with SLA-backed uptime, schema-drift monitoring, and monthly performance reviews.
Yes. We optimize and extend existing Snowflake, BigQuery, or Redshift — or migrate off them if they're the wrong tool for your scale.
Further reading.
- guide · 3 min readWhat Is a RAG Pipeline? A Plain-English Guide for Business OwnersRAG explained without jargon. How it lets AI answer from your own documents, what a pipeline is made of, what it costs, and when your business needs one.
- guide · 4 min readAI Development for Small Businesses: What's Actually Worth Building in 2026?Which AI projects pay off for small businesses in 2026, and which ones burn budget. An engineer's ranking, with real examples and honest cost expectations.
- guide · 3 min readRAG vs Fine-Tuning: Which Does Your Business Actually Need?RAG grounds an AI in your documents. Fine-tuning changes how a model behaves. An engineer's guide to picking the right one, with real production examples.
Ready to scope your Data Solutions project?
Tell us what you’re building. We’ll tell you how long it takes and what it costs, for free, in plain English.
No agency jargon. No surprise invoices. Just engineers who give you a straight answer.